
Data Centres & AI Infrastructure
What makes a building AI-ready?
Four tests of AI readiness for a building and a six-step assessment for one priority use case.
Data Centres & AI Infrastructure
Write a data specification with named owners before an AI project starts.
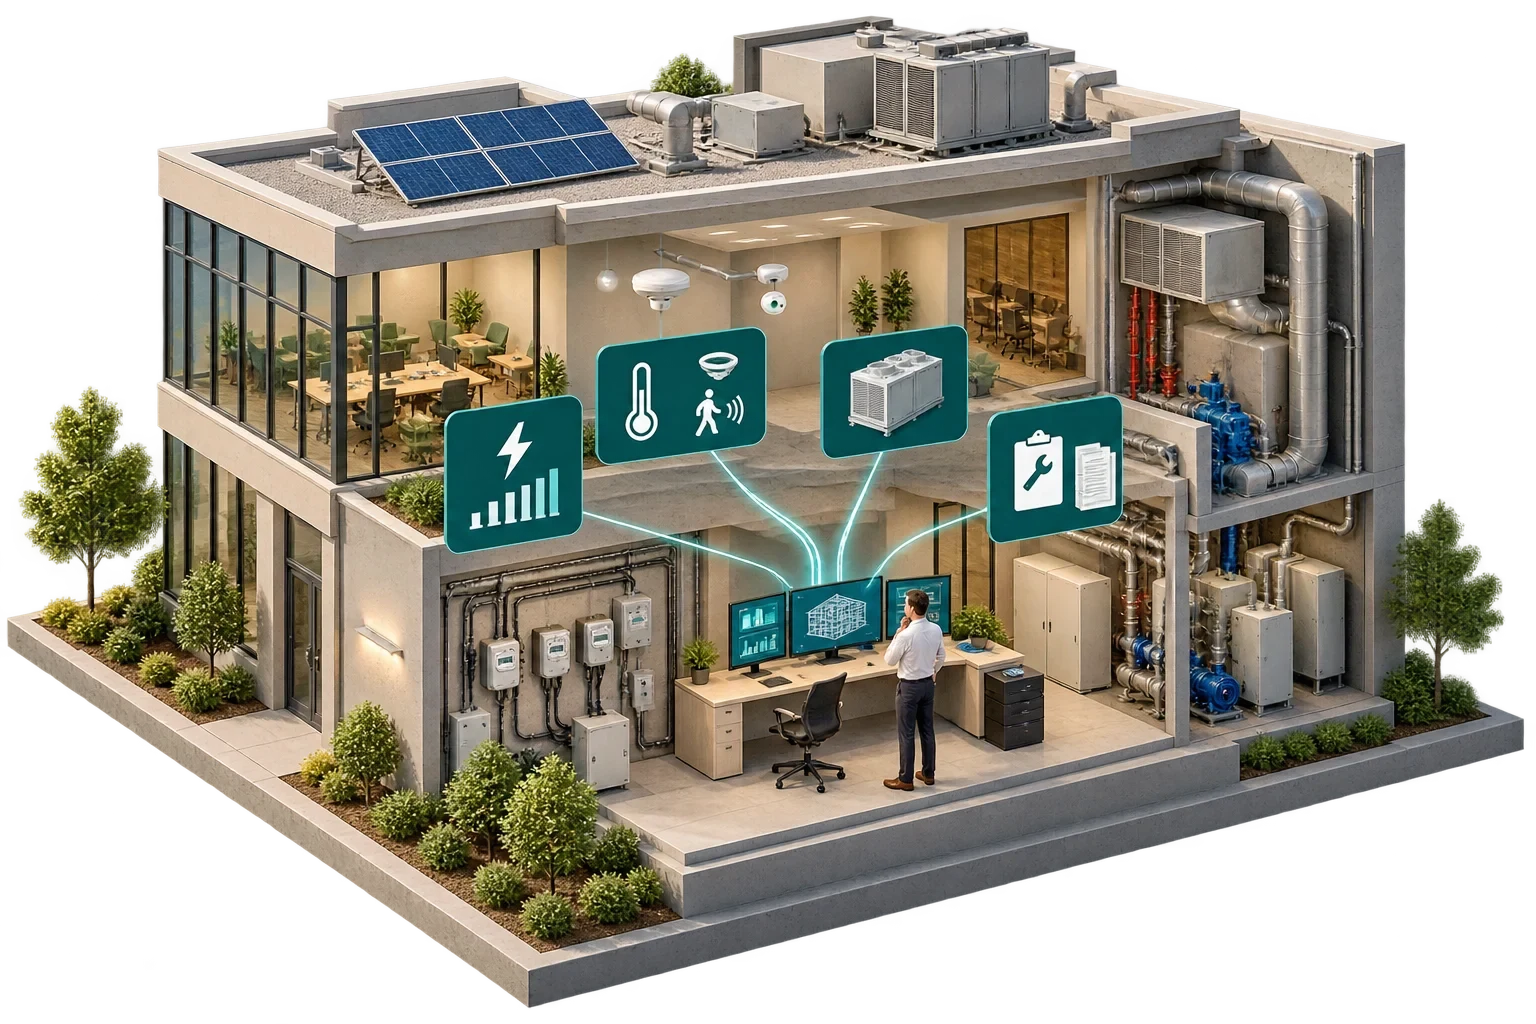
No single list fits every building. The data a building needs depends on the decision the AI is meant to support, and an energy forecast, a fault-detection tool, a document assistant and a predictive-maintenance model each want different inputs, at different frequencies, with different depths of history. So work backwards from the use case to the minimum reliable evidence it requires. Collecting everything and hoping value turns up later is the expensive alternative.
A point reads "37". It might be a valve 37% open, a command to open it that far, or a return-water temperature in degrees Celsius. For a model to use it, someone has to record which device it comes from and what that device serves, its unit, whether it is a measurement, a set point or a command, and when and how often it was sampled. What the plant was doing at the time matters too.
Semantic models such as Brick hold that context in a form software can read, so an application can ask for "all supply-air temperature sensors on air-handling units serving the third floor" without an engineer first deciphering point names by hand.
| Use case | Core data | Context and history |
|---|---|---|
| Energy forecasting and analysis | Interval meter data (e.g. 15-minute), weather | Occupancy or opening hours, schedules, a year or more to cover seasons |
| Fault detection on HVAC | Trend data for temperatures, valve and damper positions, fan status, set points | Equipment-to-point mapping, operating modes, design values |
| Predictive maintenance | Sensor history plus equipment run hours | Structured maintenance records linked to asset identities, actual failures |
| Document assistant | Approved manuals, procedures, drawings | Version control, asset links, access permissions |
Treat the table as a starting point: the supplier of any specific application should state its own requirements, and you should test them against what the building actually holds.
Completeness, accuracy, timeliness and consistency all matter, but they need to be judged over representative periods, since a convenient week can make almost any dataset look sound. NIST's AI Risk Management Framework (AI RMF 1.0) says accuracy measurements should be paired with clearly defined, realistic test sets that represent the conditions of expected use. For a building, the question is whether the history covers what the application will actually meet: every season, holidays, changes in occupancy, plant failures. A dataset drawn from one mild spring cannot support claims about summer peaks.
Tolerances differ by use case as well, so agree acceptable gaps and latency for each one. A monthly energy trend can live with a few missing hours; an operational alert cannot.
Buildings do not stand still. Sensors are replaced, recalibrated or moved; schedules change; point names are revised after a BMS upgrade. Any of these can change what a dataset means without a single value looking wrong, so a change log belongs alongside the data. NIST's framework notes that maintaining the provenance of training data supports transparency and accountability. In a building it also lets an engineer explain why a model's output shifted.
Data preparation is often the largest task in an early building AI project, and the one most likely to be missing from the budget. Someone has to map points to assets and spaces, set quality checks and their thresholds, correct errors at source as well as in the analytics copy, log changes to sensors, schedules and systems, and keep the mapping current as the building evolves. Unless each of those tasks has a named owner, the model inherits the gaps.
Write down the data the model needs, who maintains each part and how quality will be checked, while the choice of model is still open. That specification costs little next to the software it feeds, and it decides whether anyone should trust the output.
This article connects to our work on Our services.
We can discuss infrastructure and data readiness.
Contact Pagin Consulting